FreeFuse could not hand-parse thousands of videos. We built the pipeline that does it.
FreeFuse's interactive video platform turns footage into branching, viewer-directed paths — but every segment was cut and placed by hand. Neuramonks delivered a vision and NLP pipeline that segments and structures this non-linear video content automatically.

Delivered for FreeFuse
- 60%
- Less manual structuring
- 35%
- Higher viewer engagement
- 40-50%
- Faster content onboarding
- 1000s
- Videos structured at scale
Delivered for the L&D team
- 60%
- Less manual structuring
- 35%
- Higher viewer engagement
- 40-50%
- Faster content onboarding
- 1000s
- Videos structured at scale
The Client's Problem
Editorial judgement, applied by hand, to thousands of videos.
- Segments cut and placed by human judgement
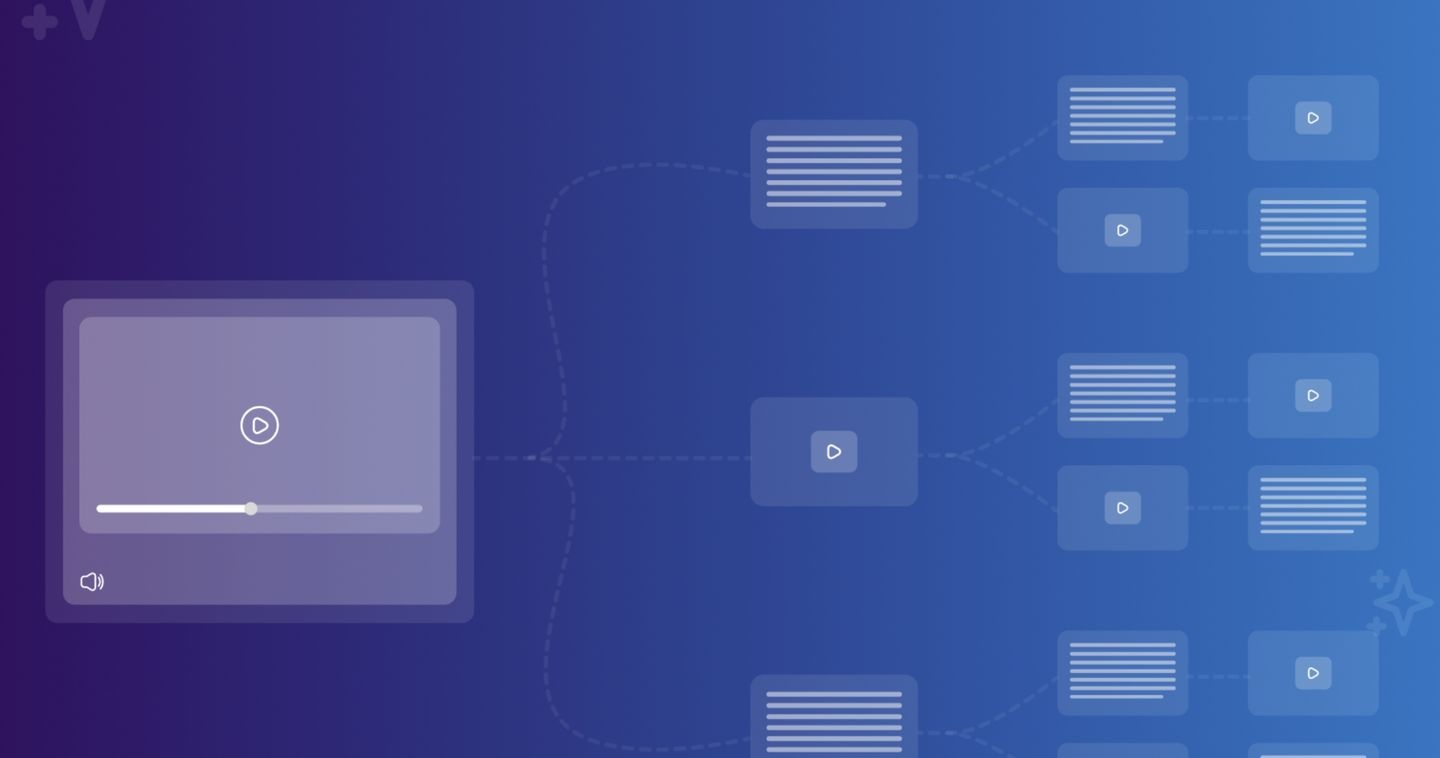
- Vision and NLP models segment automatically
- Tree structures assembled manually per video
- Hierarchy generated from the content itself
- Content volume capped by editor hours
- Onboarding accelerated by 40–50%
What We Delivered
Six pieces of work, one working pipeline.
- 01 · Computer Vision
- Scene and transition detection
- Finds objects, scenes and cut points inside each frame.
- 02 · NLP Engineering
- Dialogue and context analysis
- Reads spoken audio and on-screen text for meaning.
- 03 · Applied Research
- Coherent segmentation
- Splits video into micro-segments that stand alone.
- 04 · Structural AI
- Tree hierarchy generation
- Organises segments into a navigable branching structure.
- 05 · Platform Engineering
- AWS processing architecture
- Scales to 1000s of videos monthly without queue backlogs.
- 06 · Integration
- Cross-platform playback
- Consistent interactive playback across devices and operating systems.
- Across all six · Media assets
- Encrypted end to end
- Source video and derived segments encrypted in transit and at rest.
- Access-controlled by role
- Creators, reviewers and admins see only their own scope.
- On-prem capable
- Deployable on-premises or air-gapped where policy requires it.
Content pipeline capped by human hours?
Our AI video segmentation developer scopes which pieces your build needs, in 30 minutes.
The Result
Editorial judgement, running at machine scale.
The pipeline reproduces the segmentation calls a human editor would make, then builds the tree around them — so the catalogue grows without editing hours growing with it.
60%
Less manual structuring effort, with viewer engagement depth up 35% once paths were generated automatically.
How The Engagement Ran
Four phases, judgement to production.
- Phase 1
- Discovery
- Human segmentation logic captured from the editorial team.
- Phase 2
- Vision and NLP models
- Scene detection and dialogue analysis trained on their catalogue.
- Phase 3
- Hierarchy engine
- Segment coherence and tree generation tuned against manual examples.
- Phase 4
- Scale and rollout
- AWS pipeline optimised, cross-platform playback verified.
- Python
- TensorFlow
- Computer Vision
- NLP
- MongoDB
- AWS
Why Neuramonks
Why FreeFuse chose Neuramonks.
- Outcome-driven delivery
- Scalability and engagement targets for the interactive video platform set before development started.
- Vision and NLP since pre-GPT
- Production models shipped long before the current wave.
- Built for media volume
- High-volume ML pipelines, not demo throughput.
- Deployable on your terms
- On-premises or air-gapped where policy requires it — see our services.
Common Questions
What teams ask about this build.
How does AI segment a video automatically?
Computer vision reads scenes, objects and transitions while NLP analyses dialogue and on-screen text, so cuts land where the content actually changes.
What is a tree-based, non-linear video structure?
Linked optional segments a viewer can explore in any order, rather than one fixed timeline played from start to finish.
What did the engagement include?
Vision models, NLP pipelines, the segmentation and hierarchy engines, the AWS processing architecture, and cross-platform playback.
How is video content secured?
Source video and derived segments are encrypted in transit and at rest, with role-based access and on-premises deployment available.
Can automated segmentation match human editors?
It reproduces the coherence judgements editors make, cutting manual structuring effort by 60% while running at machine scale.